One Pad at a Time: How Short-Term Thinking in Architecture Is Setting Your Team Up to Sink
There's a certain kind of engineering meeting that happens at almost every growing tech company in America. The team is staring at a performance bottleneck, a database that's groaning under load, or an API that's starting to crack at the seams. Someone proposes a fix. It's clever, it's fast, it'll work. The team ships it. Everyone moves on.
Six months later, that fix is the reason you can't scale to the next tier of customers.
At RibbitSol, we call this the lily pad problem. A frog doesn't leap to the far shore in one jump — it hops from pad to pad. That's fine when the pads are plentiful and well-spaced. But when your engineering team keeps optimizing for the pad they're standing on right now, without thinking about the trajectory of the next leap, those pads start working against you.
Why Smart Teams Keep Making This Mistake
Here's the uncomfortable truth: the lily pad problem isn't a symptom of bad engineering. It's often a symptom of good engineering under the wrong constraints.
When you're a startup burning through runway, or a mid-market SaaS shop trying to hit your Q3 growth targets, the pressure to ship fast is real. Architecture discussions that stretch beyond the current sprint start to feel like luxuries. "We'll refactor when we need to" becomes the unofficial engineering motto, and honestly? For a while, it works.
The problem is that architectural debt compounds differently than feature debt. A half-finished feature is visible. A database schema that was designed for 10,000 users but is now serving 500,000 is invisible — right up until the moment it isn't.
Consider what happened to a mid-sized e-commerce platform a few years back (you've probably read a version of this story on every engineering blog). They built their inventory management system around a relational database with a schema tightly coupled to their original product catalog structure. It was fast, it was simple, it worked great for their first two years. Then they tried to expand into a marketplace model with third-party sellers. The schema couldn't accommodate the new data relationships without a full rewrite. They ended up running two parallel systems for almost 18 months — paying the operational cost of both — before they could fully migrate.
The fix they shipped in year one wasn't wrong. It was just optimized for a lily pad they were never going to stay on.
The Patterns That Paint You Into a Corner
Not all short-sighted architectural choices look the same. A few patterns show up again and again:
Hardcoded assumptions about data volume. Designing indexes, query patterns, or caching layers based on your current data size is one of the fastest ways to create future pain. What's performant at 50GB can be catastrophic at 5TB.
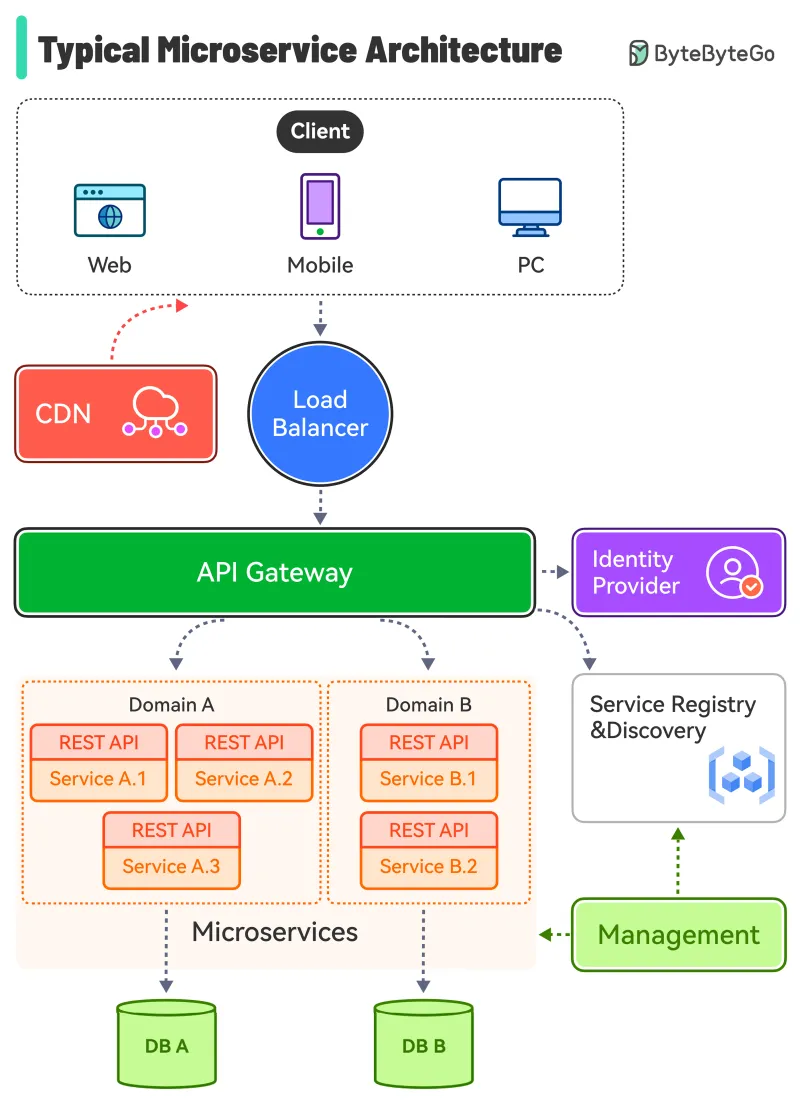
Tightly coupled services that made sense early on. When you're small, having your authentication logic baked into your main application feels fine. When you want to launch a mobile app, a partner API, or a white-label product, that decision suddenly costs you months.
Infrastructure sized for today's traffic. This one's gotten a lot better with cloud-native tooling, but plenty of teams are still running fixed-capacity setups — or cloud configurations that don't auto-scale sensibly — because "we haven't needed more than this yet."
Vendor lock-in disguised as convenience. Leaning heavily on a single cloud provider's proprietary services can feel like the path of least resistance. And sometimes it genuinely is the right call. But when your entire data pipeline is built on managed services that don't have equivalents elsewhere, you've traded flexibility for speed — and that trade-off should be a conscious choice, not a default.
Thinking Ahead Without Over-Engineering
Here's where a lot of teams overcorrect. They hear "design for scale" and start architecting for ten million users on day one. They build distributed systems before they have distributed problems. They introduce complexity that their team can't maintain and their product doesn't yet need.
Over-engineering is just the lily pad problem pointing in the other direction. You're still not thinking clearly about the trajectory — you're just jumping too far ahead instead of not far enough.
A more useful mental model is what we'd call the next-pad test. Before you ship an architectural decision, ask two questions:
- What does this look like when our usage doubles? Triples?
- What would we have to undo if we wanted to change direction in 18 months?
You don't need to have perfect answers. You just need to make sure your team has asked the questions and documented the trade-offs. An architectural decision that paints you into a corner isn't automatically wrong — sometimes it's the right call for where you are. But it should be a deliberate choice, not an oversight.
Building a Scalability Checkpoint Into Your Process
Practically speaking, the teams that handle this best tend to do a few things consistently:
They write lightweight Architecture Decision Records (ADRs). Not epic design docs — just a short note that captures what was decided, why, and what the known limitations are. When you revisit that decision in a year, you'll know what you were optimizing for at the time.
They do a brief "scale review" for any infrastructure or data model changes. This doesn't have to be a formal process. Even a five-minute conversation at the end of a design review — "what breaks first if this gets 10x bigger?" — surfaces issues that would otherwise stay invisible.
They distinguish between reversible and irreversible decisions. Jeff Bezos famously called these Type 1 and Type 2 decisions. Reversible choices can move fast. Irreversible ones — like database schema design, API contracts, or authentication architecture — deserve more deliberate thought.
They invest in observability early. You can't reason about scalability if you can't see what's actually happening in your system. Teams that instrument their applications well from the start are the ones who spot the next bottleneck before it becomes a crisis.
The Leap Worth Taking
Scalability isn't about predicting the future. No engineering team has a crystal ball, and anyone who tells you they designed a system that could handle any growth trajectory without ever revisiting it is selling something.
What scalability really comes down to is building systems that are honest about their limits and easy to evolve. It's the difference between a lily pad that holds your weight today and one that's also positioned for where you actually need to jump next.
The teams that get this right aren't necessarily the ones with the most experienced architects or the biggest infrastructure budgets. They're the ones who've built the habit of looking up from the current pad long enough to ask: where are we actually trying to land?
That question, asked consistently and early, is worth more than any amount of clever engineering after the fact.