The Failures That Blend In: Hunting Silent Errors in Distributed Systems
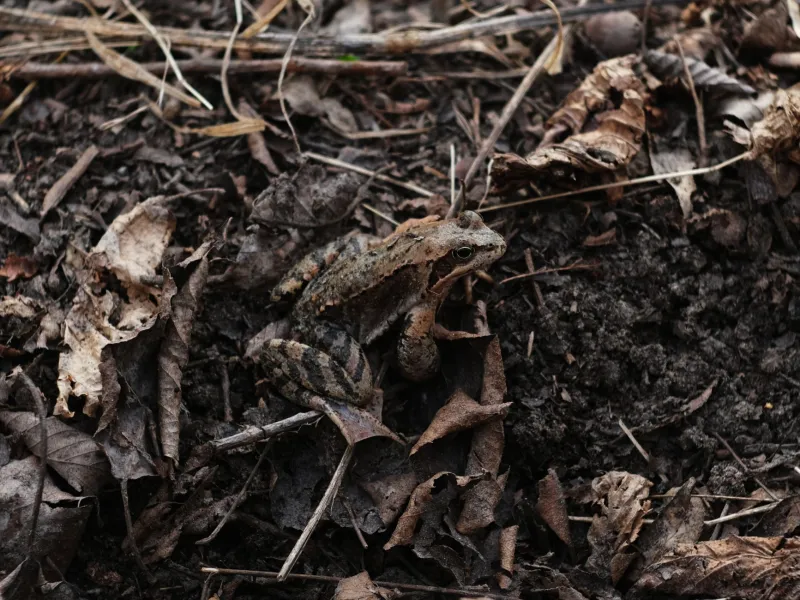
There's a species of frog that looks exactly like a dead leaf. It can sit on the forest floor and practically every predator walks right past it. Distributed systems have failures like that too — the kind that blend so perfectly into normal operational noise that your monitoring walks right past them every single day.
Your dashboards are built to catch the loud stuff: 500 errors, latency spikes, services falling over entirely. But the failures that actually erode reliability over months are quieter. They look like the background. And that's exactly what makes them dangerous.
Why Silent Failures Are Worse Than Loud Ones
A crash gets a page. An engineer wakes up, fixes it, writes a postmortem. Annoying, but the system learns.
A silent failure gets nothing. Every retry succeeds 'eventually,' every dropped message gets papered over by a timeout, every degraded service keeps answering just enough to stay green. The system never gets a chance to learn because, as far as your observability stack is concerned, nothing ever happened. Users feel it as a vague sense that your product is 'slow sometimes' or 'loses stuff occasionally' — feedback that never makes it into a ticket.
The Five Blind Spots That Hide in Plain Sight
Run through this list against your own stack. If you can't say confidently that each one is covered, you've got camouflage in your pond.
1. Silent retries masking upstream rot. When a client retries a failed call and the retry succeeds, the failure vanishes from your metrics — but the latency, the load, and the user experience damage don't. Track retry rates as a first-class signal, not just success rates. A success rate of 100% with a retry rate of 15% is not a healthy system.
2. Messages dropped at the edges. Consumers crash mid-batch, offset commits fail, messages expire on dead-letter queues nobody looks at. If you don't have an alert on DLQ depth and consumer lag trending, you have a hole where data quietly disappears. Reconcile counts at ingestion versus processing — the gap is where your lost events live.
3. Degraded-but-alive dependencies. A third-party API that starts returning stale data instead of errors is still 'up.' A database replica running 30 seconds behind is still 'healthy.' Health checks that only verify a service responds will happily report green on a system that's lying to you. Check for freshness and correctness, not just liveness.
4. Timeout budgets that hide cascading slowness. When Service A times out waiting on Service B, and B's timeout waiting on C is even longer, you get request trees where the caller gives up but the work keeps churning downstream. Distributed tracing with proper span timing will expose these cascades — but only if you actually look at the tail latency percentiles, not the averages. p99 is where the camouflage fails.
5. Background jobs failing without witnesses. Nightly syncs, cache warmers, report generators — cron jobs that fail silently are the classic blind spot because nobody's watching at 3 a.m. Synthetic checks that run the critical paths on a schedule, with alerts on absence of success (not just presence of failure), close this gap.
Building a Camouflage-Hunting Toolkit
Three tools do most of the heavy lifting:
Distributed tracing gives you the request-level story across service boundaries. Tools built on OpenTelemetry make it realistic for teams of any size. The key discipline: trace the unhappy paths deliberately. Force failures in staging and confirm your traces actually show what broke.
Synthetic monitoring runs your critical user journeys on a schedule, from outside your own infrastructure, so you catch failures that internal health checks are structurally blind to.
Anomaly detection on the boring metrics. You don't need ML sophistication to catch most silent failures — you need alerts on rate-of-change. Retry rate doubled? DLQ grew at all? Replica lag trending up for six hours? Those are leaf-shaped blips on a trunk that looks like a leaf, and simple thresholding catches most of them.
Make the Invisible Visible, Then Make It Loud
The goal isn't a monitoring setup so sensitive it pages you for breathing. It's making sure that when something fails, it fails visibly — with a signal, an owner, and a path to a fix. Camouflaged failures don't get postmortems. They get folklore ('the search has always been a little weird') and they compound.
Audit your blind spots this quarter. The failures you can't see aren't waiting politely. They're sitting perfectly still, looking exactly like a dead leaf, while your reliability rots underneath you.